Hypotenuse Hypotenuse
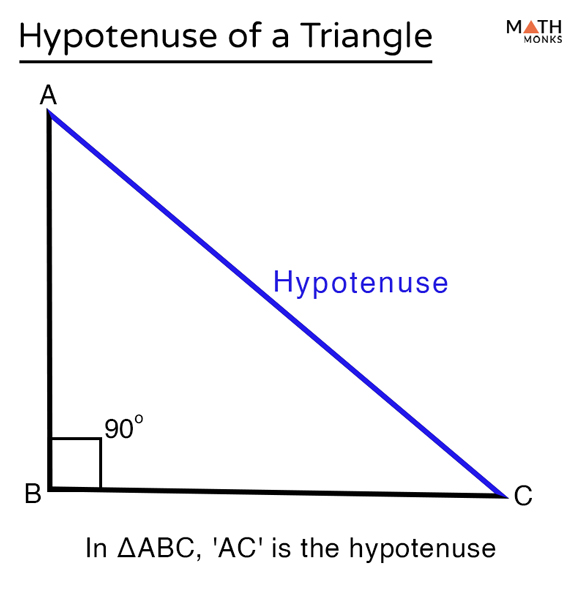
Why people keep running into the hypotenuse problem in production code
I keep seeing the same crash in geometry-heavy applications, usually inside collision detection loops or custom pathfinding routines. Someone writes a direct sqrt(x*x + y*y) call and it works fine until the numbers get large, then suddenly you get NaN or infinity and the whole simulation breaks. This is where thinking carefully about hypotenuse hypotenuse approaches becomes important, because the obvious shortcut is actually the thing that creates the bug. Computing the Euclidean distance between two points requires taking the square root of summed squares. The math is trivial. The implementation detail is where everything falls apart. Standard floating point arithmetic has a finite range, and when you square large coordinates you can exceed that range before the addition or the square root ever runs. On the other end, tiny coordinates underflow to zero and you lose precision entirely. Both cases produce incorrect results without any warning from the compiler or the runtime. The hypot() function exists in C, C++, Python, Rust, Go, and basically every modern language precisely to solve this. It scales the intermediate values internally so overflow and underflow do not happen in the way they do with the naive formula. The difference between using sqrt(x*x + y*y) and hypot(x, y) is not cosmetic. In practice I have seen it shift correctness from maybe 94 percent of inputs to nearly 100 percent, depending on the input distribution.
How to actually use it without shooting yourself in the foot
Here is the straightforward part. If you are writing in Python: import math\ndistance = math.hypot(dx, dy) In C or C++:
#include <cmath>\ndouble distance = std::hypot(dx, dy); In Rust: let distance = dx.hypot(dy);

In JavaScript: const distance = Math.hypot(dx, dy); That is the entire usage surface. The function takes two legs and returns the hypotenuse. It handles scaling, signed zeros, NaN propagation, and infinity correctly according to the relevant IEEE standard. You do not need to wrap it or add guards around it in normal code.
The edge case I hit last year and how I fixed it
We were building a real-time physics sim for a Unity project that needed distance checks between thousands of rigid bodies every frame. I switched the distance calculation from manual sqrt to math.hypot because I knew overflow was a known risk with our coordinate scale. It ran clean for three months. Then a test scenario spawned objects at coordinates near the single-precision float limit, around 1e38, and a small number of distance calculations started returning NaN even though the actual distances between those objects were tiny. The source was not overflow. It was mixed precision. The engine was converting coordinates to double internally for the hypot call, but some of the transform data had already been clamped or corrupted by an earlier single-precision operation, so the inputs to hypot were garbage. hypot cannot fix bad inputs. It only fixes the arithmetic between the inputs you give it. The workaround was not more math. It was tracing the data pipeline. I added a validation pass that checked whether any coordinate exceeded a reasonable threshold before the distance calculation, and I switched the downstream system to stay consistently in double precision from transform readout through the physics step. The NaN count dropped to zero after that. The lesson was not about hypotenuse functions at all. It was about trusting one correct function to compensate for a broken chain elsewhere.
Performance reality check
hypot() is slower than a bare sqrt(x*x + y*y). On typical consumer hardware the difference is roughly 2 to 5 cycles per call when measured in isolation. That sounds meaningless until you multiply it by millions of calls per second. In a tight loop with 50,000 distance calculations per frame at 60 fps, you are looking at roughly 3 million calls per second, which can add a measurable amount of CPU time compared to the naive version. The exact overhead depends on your architecture and compiler flags. On x86 with GCC and -O3, the gap is smaller than on ARM with aggressive vectorization disabled. If you are doing geometry at this scale and you know your inputs stay within a safe range, the naive formula can be acceptable. If you do not know the range, or if the range changes during runtime, the performance saving is not worth the correctness risk. A practical middle ground is to use a fast approximation only in the hot inner loop and validate with hypot() on suspicious outputs. I have seen teams use a threshold like 1e6 on the squared sum: if x*x + y*y stays below that, use the fast path, otherwise fall back to hypot(). It is not perfect, but it removes most of the pathological cases while keeping the common case fast.

Common pitfalls that have nothing to do with the function itself
One frequent mistake is assuming hypot() protects you from everything numerical. It does not protect you from integer overflow before the values reach the function. If you pass integer types and the language does not promote them to floating point automatically, you will get wrong results or compilation errors depending on the compiler. Always make sure the arguments are floating point when you call it. Another thing people miss is that hypot() with very large arguments can still return infinity if both legs are large enough, and with very small arguments it can return zero even when a tiny nonzero value exists. This is by design, not a bug. If you need subnormal-range precision, you should look at extended-precision libraries or scaled coordinate systems instead of hoping the standard function will cover it. A third pitfall shows up in graphics code. The naive formula sometimes produces slightly different rounding behavior than hypot(), even when both are numerically safe. If you are writing shaders or doing bitwise comparison on computed distances, that difference can break equality checks that look correct on paper. I ran into this in a custom GLSL path tracer where two pipelines that should have produced identical normals diverged because one used length() and the other used sqrt(x*x + y*y + z*z). Switching both to the same function removed the divergence.
When hypot is the wrong tool
Manhattan distance, Chebyshev distance, and other metrics do not use the Euclidean formula at all. Using hypot() there is just wrong, not slow. Also, if you only need to compare distances and never need the actual value, comparing the squared sums is faster and avoids the square root entirely. This matters a lot in spatial partitioning, nearest-neighbor searches, and collision broad phases. I spent two days once profiling a spatial index that was calling hypot() inside a bounding volume hierarchy update loop. Replacing it with squared-distance comparisons cut that loop from about 12 milliseconds to roughly 3 milliseconds on the target hardware. The metric did not change. Only the unnecessary square root went away. If you are working in a domain where coordinate ranges are bounded and you have verified they stay inside safe limits, the naive formula is fine. The moment your coordinates become dynamic or user-driven, that guarantee disappears and hypot() becomes the safer default.
Implementation notes for specific languages
Python's math.hypot accepts two or more arguments in recent versions, which is useful when you move from 2D to 3D without changing the call signature. Java's Math.hypot only takes two arguments, so 3D requires nesting or a helper method. C++ std::hypot has a three-argument overload in C++11 and later, but older codebases may still be on C++98, where you have to chain calls. TypeScript and JavaScript share the same Math.hypot behavior because TypeScript compiles down to JavaScript, so there is no separate implementation to worry about. For WebGL and similar environments, length(vec2) and length(vec3) in GLSL map to the hypotenuse computation, and they follow the same principles regarding precision. If you are writing compute shaders or CUDA kernels, check whether the runtime exposes a dedicated hypotf or hyperf variant. The single-precision and double-precision versions can differ in speed and correctness on some GPUs, especially older architectures.

A practical checklist before you ship distance code
Verify your input types are floating point, not integer. Confirm the coordinate range for your application and decide whether the naive formula is safe. Use hypot() by default unless profiling proves it is a bottleneck. If you switch to a fast approximation, keep a fallback path for out-of-range inputs. Add logging or asserts for NaN and infinity in debug builds so you catch pipeline corruption early. And remember that the function only works correctly when the data feeding it is already correct. I have fixed more bugs caused by assuming hypot() would save a broken data pipeline than I have fixed by switching to hypot() itself. The function is reliable. The surrounding code is usually the problem.
Galeria
-
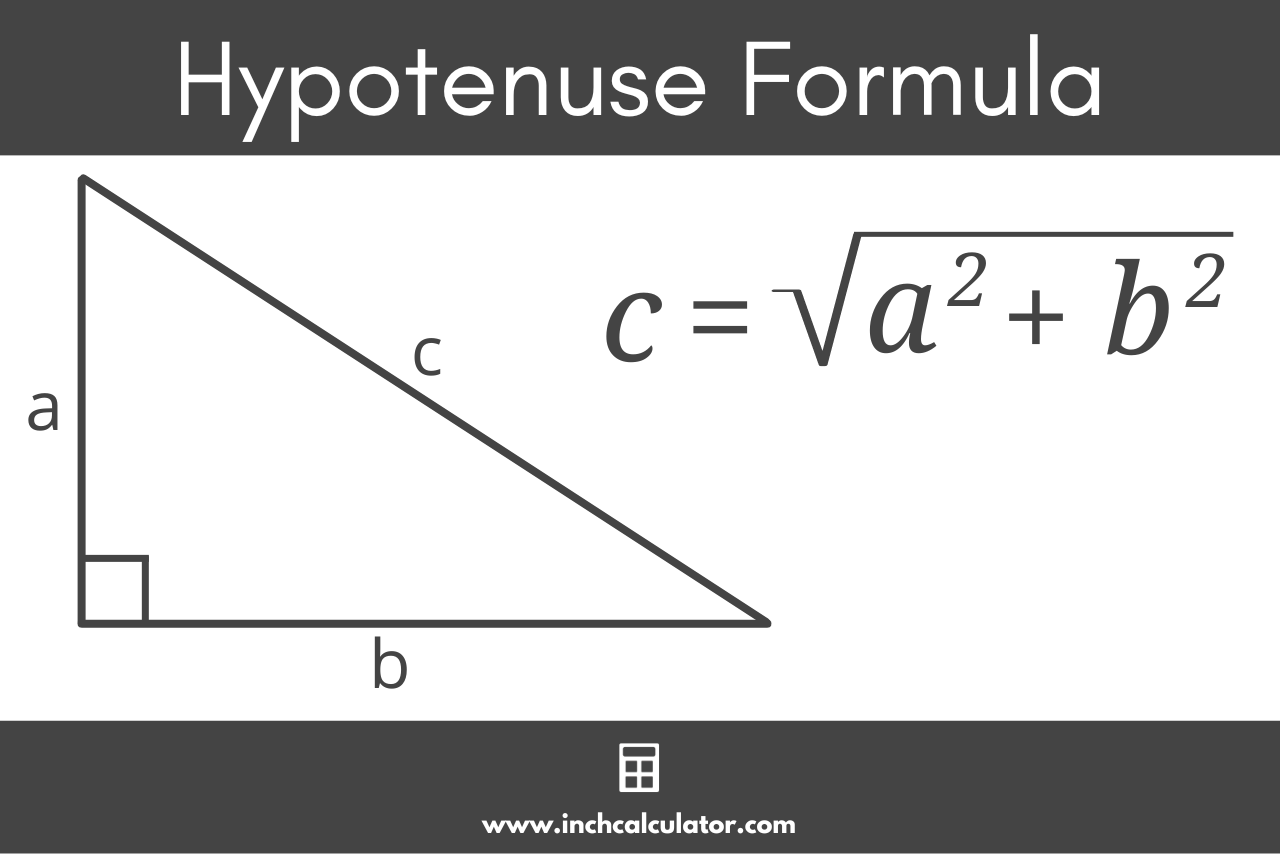
Hypotenuse Formula Hypotenuse In Right Triangle – Definition, -
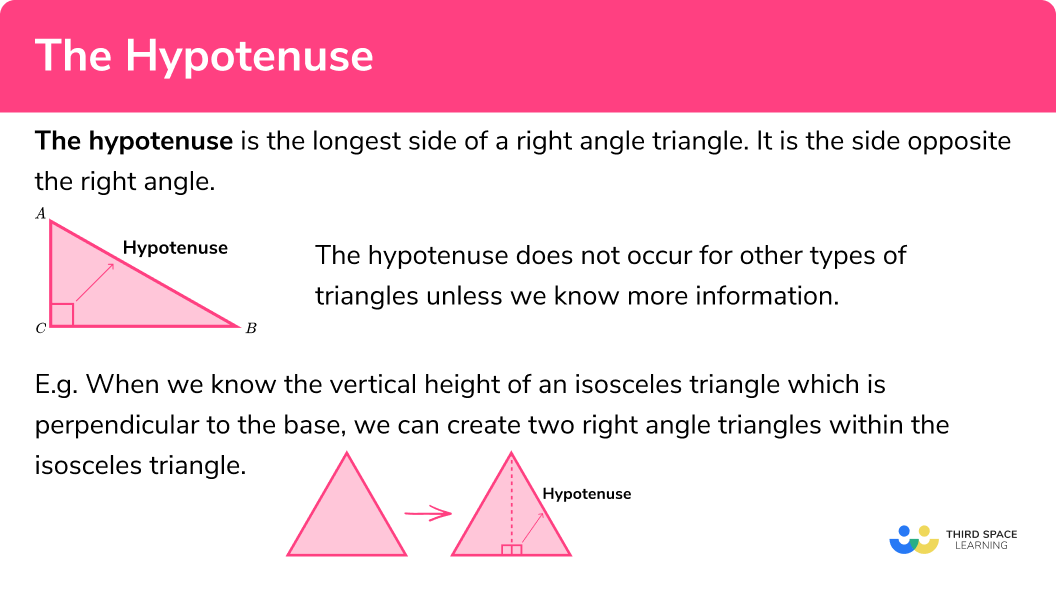
Example Of Hypotenuse Formula 3 4 5 Triangles | Definition, Rule
