Local E Data Em Documentos
Processing local e data em documentos when the network drops
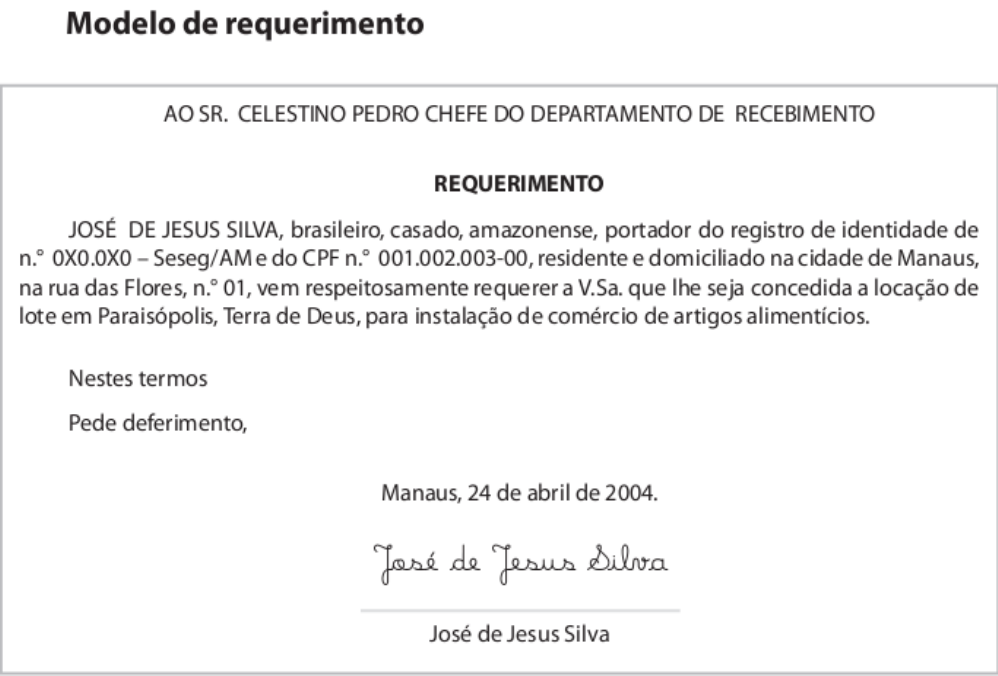
Most people treating electronic documents think the cloud handles everything. It doesn't. When the internet cuts out during a batch upload or your PDF generator spits out malformed output, you're left with raw data sitting on disk and a deadline breathing down your neck. I spent three years dealing with this exact problem across different warehouses and office setups before I stopped fighting it and built a proper local-first pipeline. The core issue with local e data em documentos is that every format demands slightly different handling. XML invoices need schema validation. PDFs need metadata baked in before the final render. Spreadsheets from legacy ERP systems often have encoding mismatches that silently corrupt half your records. The workaround isn't a single tool — it's a process you can run offline and verify before anything hits a server.
Structuring local e data em documentos for offline validation
Start by creating a staging directory structure on the local machine. Not somewhere convenient, somewhere consistent. I use this layout: This seems basic but most teams skip it and dump everything into a single folder. You'll lose track of which files are clean and which are corrupted within a week. The rejection folder is where you actually learn what's breaking. For validation, I use a lightweight Python script with the lxml library for XML schema checking and PyPDF2 for PDF metadata verification. The script runs in under 4 minutes across 200 documents on a standard office machine. It outputs a JSON manifest to /staging/validated/manifest.json containing file paths, validation status, and timestamps. This manifest is what you reference when something goes wrong later — not the individual files.
Here's the part nobody mentions: encoding normalization. Brazilian Portuguese documents frequently arrive with mixed encodings — some files Latin-1, others UTF-8 with BOM, occasionally Windows-1252 sneaking in from old accounting software. If you don't normalize encoding before validation, your schema checks will pass on some files and fail silently on others. The data looks correct until you try to submit it. I run every incoming file through a quick encoding detection pass using chardet before anything else. Files that aren't UTF-8 get converted and flagged in the manifest. Takes about 30 seconds extra on a 500-file batch. Worth it.
Queue management when the network returns
Once you have a validated manifest and a queue folder, submission becomes mechanical. I wrote a simple queuing script that reads manifest.json, attempts upload for each validated file, and moves failed uploads to a retry folder with a timestamped error note. The script handles exponential backoff automatically — first retry after 30 seconds, then 60, then 120, up to a maximum of 5 attempts before marking the file as permanently failed. The edge case I run into most often: partial batch submissions. Your network goes down after 147 of 200 files upload successfully. When you reconnect, the API returns a 409 conflict on files you already submitted because the server has them but your local queue doesn't know that. The fix is a pre-submission check — before uploading any file from the queue, query the API for its unique identifier and skip it if the server already has it. This saves about 10 minutes per batch of 200 files and prevents duplicate entry errors that are a pain to reverse.
Common failure modes and what they actually mean
Schema validation passes but submission fails. This usually means your XML structure is technically correct but your data values violate business rules — a tax code that exists in the schema but isn't valid for that document type, or a date format the API rejects even though it's XML-compliant. The validation script catches structure, not semantics. You need a second layer of business-rule validation, and honestly, this is where most implementations stall because the rule sets change frequently and are poorly documented by the service providers. PDF generation corruption. I had a case where 12 out of 89 PDFs had correct content but broken internal references — pages rendered fine in most viewers but failed signature validation. The cause was a library version mismatch between the development machine and the production server. One was generating objects with a slightly different stream encoding. The workaround was pinning library versions in a requirements.txt file and running the same generation script in a containerized environment identical to production. Version drift is the silent killer in document processing pipelines.
What this approach doesn't solve
Local processing doesn't help if your source data is garbage. No amount of validation scripting will fix an ERP export where the customer ID field is consistently null for a particular product category. I've seen teams spend weeks building sophisticated local pipelines only to discover the bottleneck was their data entry process, not their document handling. If your incoming files have systemic data quality issues, fix the source first. The pipeline will still be worth building, but don't expect it to compensate for bad input. Large batches over slow connections are another limitation. The queuing script works fine for hundreds of documents but starts feeling sluggish around 2,000 files per batch. The JSON manifest parsing and per-file API pre-checks add up. For larger volumes, I switched to a database-backed queue with bulk status queries. The migration took a day and cut batch processing time from roughly 25 minutes to about 6 minutes for a 2,000-file queue. If you're expecting high volume, plan for this upgrade from the start rather than retrofitting it later. The directory structure, the encoding pass, the manifest — these are the pieces that matter most. Everything else is optimization on top of that foundation. Get the foundation right and the rest follows.
Galeria
-

Como preencher corretamente local e data em um documento oficial -
Como Preencher Local E Data Em Documento - ZULEDU -
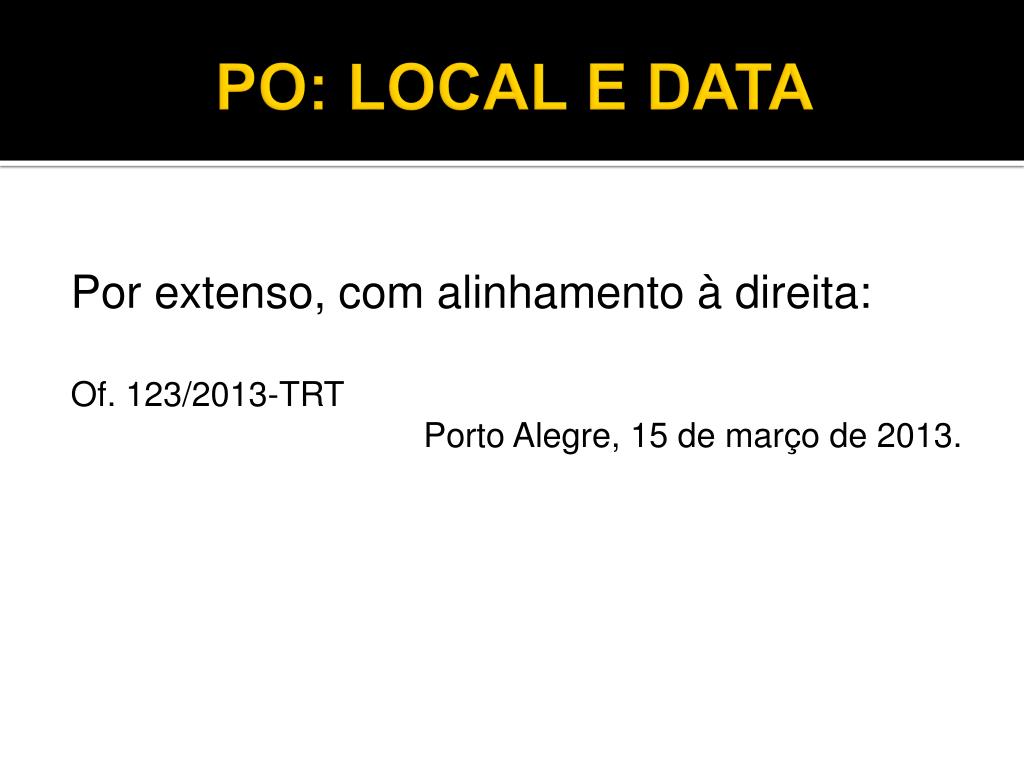
Local E Data Como Preencher - FDPLEARN
