Revolução Industrial Data

Working with industrial revolution datasets is more annoying than people admit
I spent three weeks last year cleaning a dataset labeled as factory output records from the late 1700s. What looked like a straightforward time series on the surface turned into a mess of inconsistent date formats, missing months, and columns that clearly represented different things depending on which parish the data came from. The source was a compiled collection from several UK digitization projects that never standardized their schemas before merging. If you're looking at revolução industrial data for the first time, the immediate problem is figuring out what you're actually working with before you waste days building models on garbage input. The most reliable sources I've encountered are the UK National Archives' digitized parish records, the Economic History Society's datasets, and a few university repositories like the ones at UCL and Cambridge that specialize in historical economic data. There's also the IPUS project for population statistics, though that requires some extra work to cross-reference with industrial output. Kaggle has uploaded some cleaned versions, but they're usually derived from the same primary sources, so you're getting a secondhand copy with whoever cleaned it already making decisions about how to handle gaps. My usual workflow starts by downloading raw files from the original archives rather than starting with a pre-cleaned dataset. The pre-cleaned versions make assumptions about missing values and date conversion that you might not agree with. I pull the raw CSV or Excel files, check the variable definitions in any accompanying documentation, and then write my own cleaning script. It takes longer upfront but saves you from debugging someone else's invisible decisions later.
One specific edge case I ran into involved wage data where the units switched from shillings to pounds mid-series without any note about it. The column header said "weekly wage" but roughly 40% of the observations after 1795 were ten times larger than before, which should have been an obvious red flag if I'd plotted them early. Instead I spent two days wondering why my regression coefficients were behaving strangely. The workaround was comparing against a secondary source — the Adam Smith Institute published a table of typical wages by trade and decade, and the discrepancy showed up immediately when I cross-referenced. Now I always check at least one external benchmark before proceeding past the data loading stage. Another thing nobody warns you about: the calendar problem. Many records before 1752 used the old style calendar where the new year started in March, not January. If your analysis requires precise monthly aggregation and you don't account for this, your January through March data gets assigned to the wrong year. It's a small thing that throws off seasonality adjustments and any kind of event study design. I wrote a quick conversion function that shifts the year backward by one for dates between January 1 and March 25 in pre-1752 records. Took about twenty minutes and prevented a whole class of errors. When it comes to actual tools, Python with pandas handles most of the work, but I'd recommend using the historicaldata and datetimes libraries for parsing old date formats. Standard ISO parsers will choke on things like "12 Geo. 3" or records that just say "Michaelmas term 1787" instead of giving a proper date. You'll need custom parsing rules for a significant portion of the data if you're working with primary sources.
The main limitation with almost all of this data is incompleteness. Factory inspection reports don't exist before the 1830s in any systematic form. Parochial records are patchy by region. Population and employment figures are estimates at best, often backfilled decades later by historians who had to guess. If you're doing quantitative work, you need to be comfortable with imputation and aware that your confidence intervals should reflect the uncertainty in the underlying records, not just the statistical noise. A lot of published work treats these datasets as if they're complete and accurate, which they're not. For visualization, I stick to basic line charts and scatter plots. There's no need for fancy dashboards with historical data — the story is usually in the trends and the outliers. Matplotlib is more than enough and you won't spend hours tweaking colors that don't matter. If you need a starting point, the UK Data Service has a curated collection under their economic history section. It's not perfect but it's better organized than most individual project pages. Download the readme files too, because the variable descriptions there are where most of the important context lives.
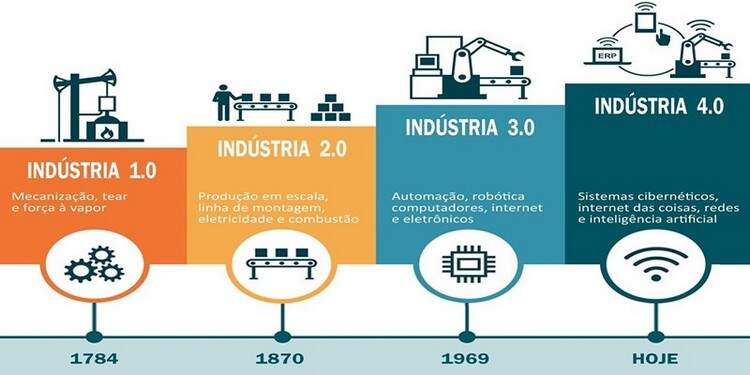
Galeria
-
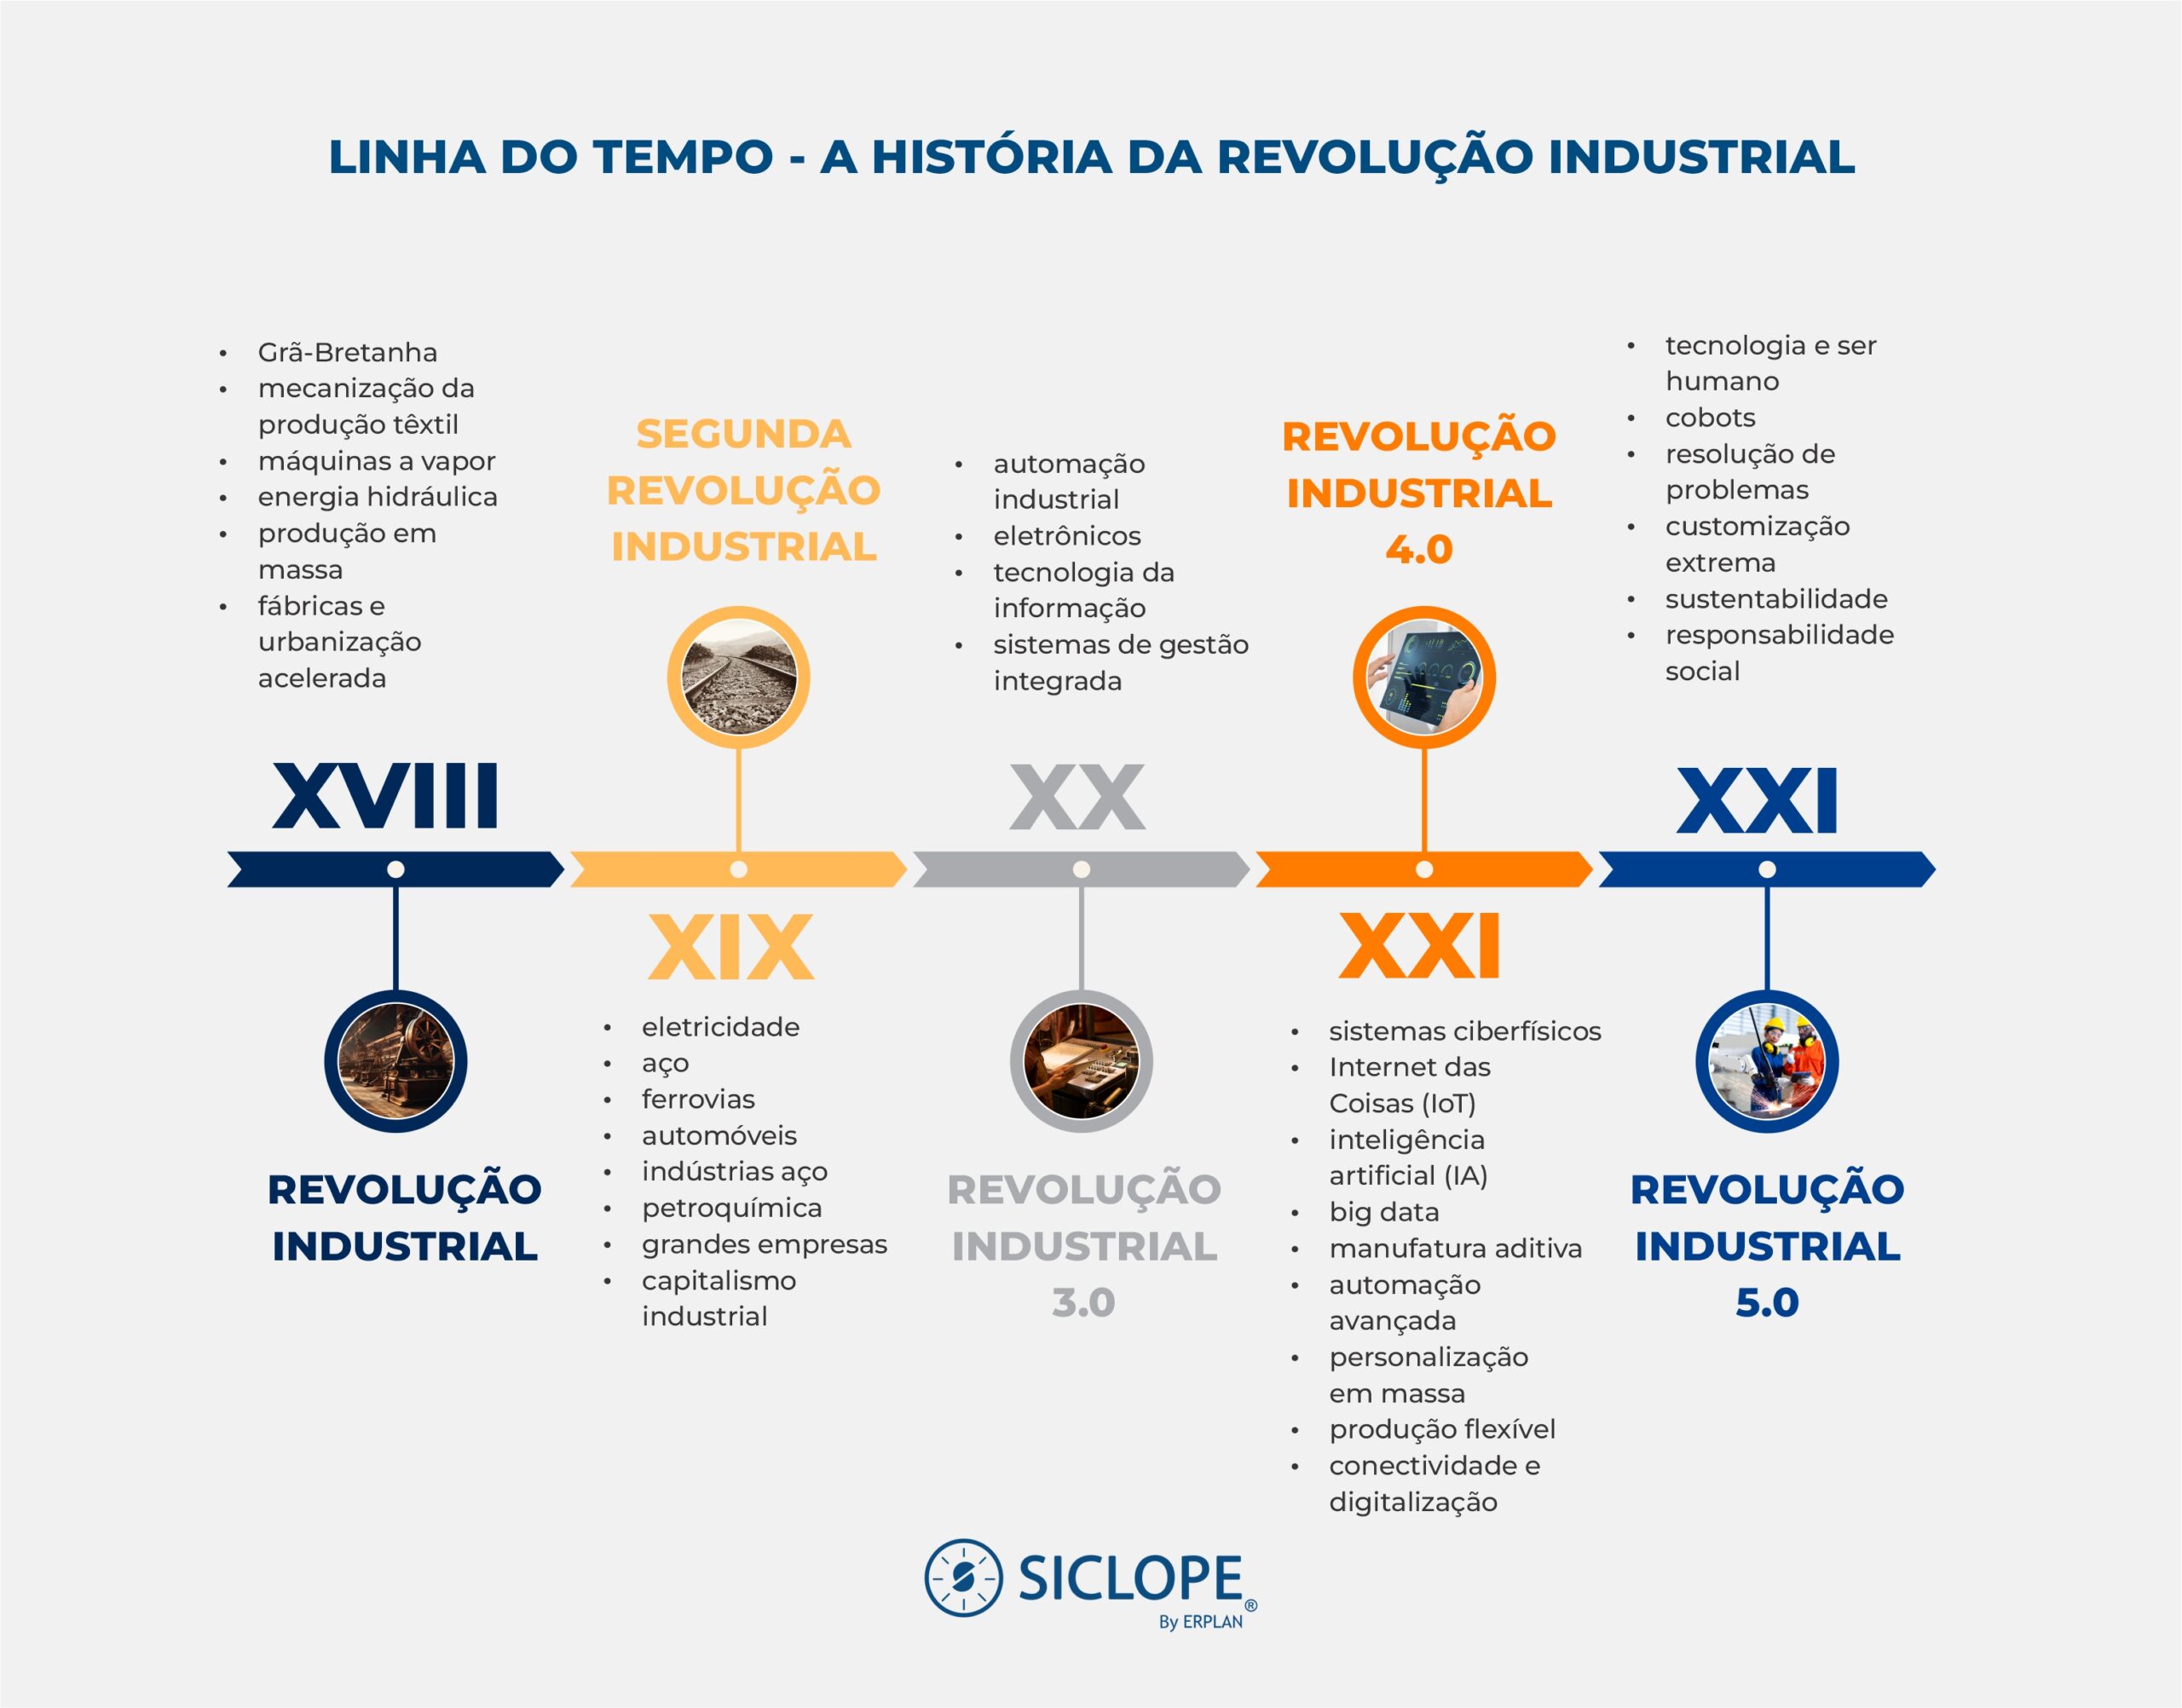
A Linha Do Tempo Das Invencoes Da Revolucao Industrial -
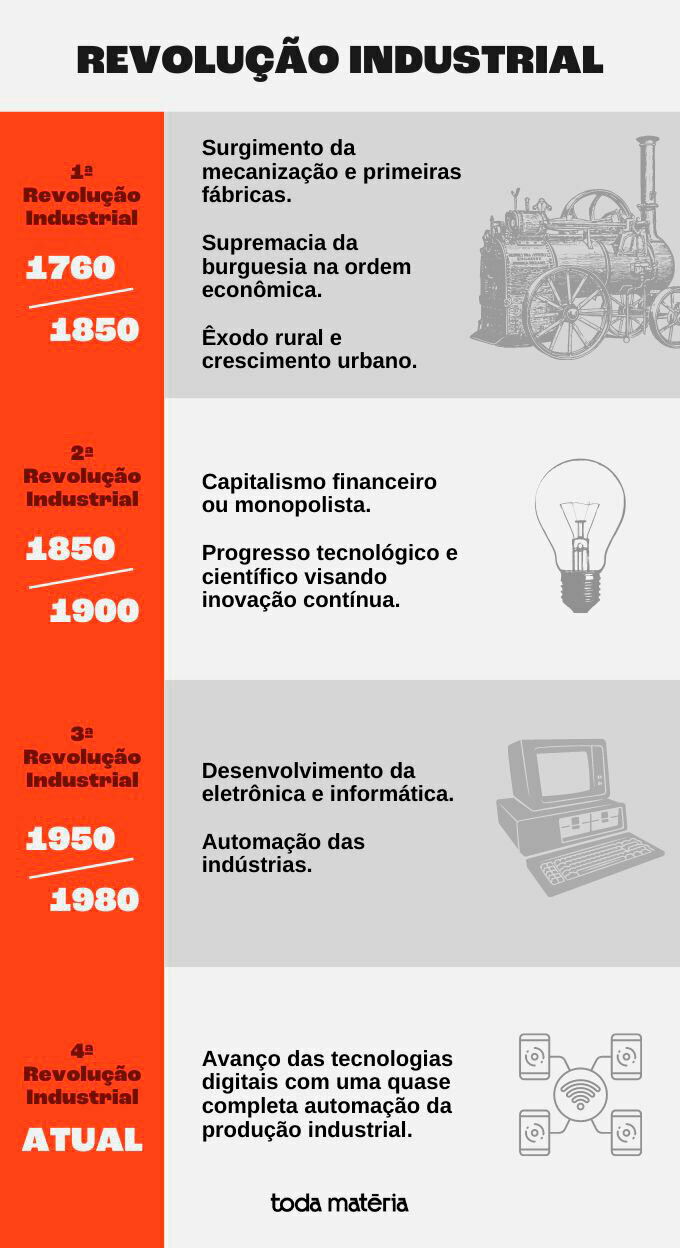
Mapa Mundial Da Revolucao Industrial -
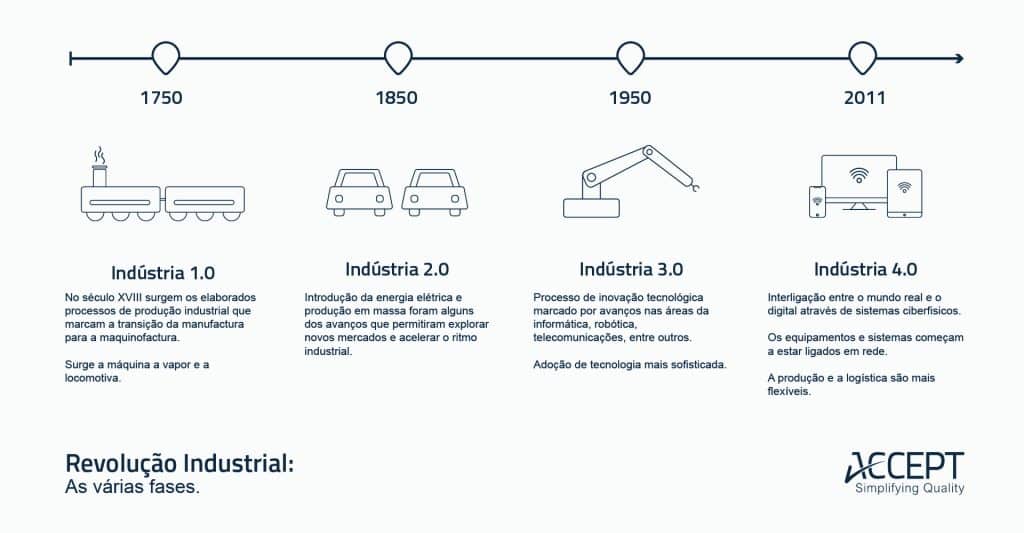
Linha Do Tempo Da Revolucao Industrial De 1750 A 1850 Projeto Banda De -
Linha Do Tempo Da Revolucao Industrial De 1750 A 1850 Projeto Banda De

