Silaba Tonica De Nariz

Working with nasal stress syllables in Portuguese
I spent a few hours last week trying to process audio files for a linguistics class where students were mispronouncing nasal vowels with wrong stress placement. The problem was subtler than it first appeared. Most people think nasal pronunciation is just about adding a nasal quality to vowels, but when you combine that with syllable stress patterns, things get messy fast. I needed a reliable way to identify and mark the silaba tonica de nariz in transcriptions, so I built a small pipeline using Praat scripts and some custom segmentation rules. The core issue is that Portuguese has four nasal vowels: /ã/, //, /ĩ/, /õ/, /ũ/, and each one can fall on a stressed or unstressed syllable. When the stress lands on a nasal vowel, you get what we call a nasal stressed syllable. The tricky part for beginners is that not all nasal vowels are created equal in terms of phonetic realization. A nasal /ã/ in a stressed position sounds noticeably different from an unstressed /a/ followed by an /m/ or /n/ coda consonant. Here is the practical workflow I ended up using:
First, I run the audio through a forced alignment tool like Mont real Forced Aligner or Montreal's English-French variant adapted for Portuguese. The alignment gives me phoneme-level timestamps, which is where most people stop, but that is not enough. I then cross-reference those timestamps with a vowel quality analyzer script that measures formant trajectories (F1 and F2) specifically around the nasal vowel window. Nasal vowels have a characteristic lowered F1 and raised F2 compared to their oral counterparts, and the difference is more pronounced on stressed syllables. The script I wrote compares the formant values in the nasal vowel region against baseline measurements from a reference corpus of European and Brazilian Portuguese speakers. If the formant pattern matches the nasal profile and the stress annotation from the aligner marks that syllable as stressed, it flags it as a silaba tonica de nariz. Simple in theory, but the edge cases are where it gets annoying. One specific problem I ran into involved words like "cântico" versus "cântica". The stress falls on the same syllable position, but the surrounding phonetic context changes the nasal quality dramatically. In "cântico", the /ã/ is followed by a velar stop /k/ and a voiceless fricative /s/, while in "cântica" it is followed by /k/ and a voiced affricate-like environment. My initial script was flagging both as nasal stressed syllables correctly, but the acoustic measurements were off by about 15 hertz on F1 because the following consonant context was pulling the formants differently. I fixed this by adding a contextual normalization step that accounts for the place and manner of the following consonant. It added maybe twenty minutes to the processing time per file, but the accuracy jump was worth it.
Another common pitfall is what happens with diphthongs. Words like "pé na praia" have a stressed nasal vowel in a diphthongal context, and the stress boundary doesn't always line up neatly with the phoneme boundaries from the aligner. You end up with cases where the aligner marks the stress on the second element of the diphthong, but acoustically the nasal quality peaks on the first element. I solved this by looking at the energy contour within the diphthong and finding the point of maximum spectral noise, which roughly corresponds to the true stress peak for nasal vowels.
When this approach breaks down
It does not work well with rapid speech. If someone is talking at a conversational pace above about 180 syllables per minute, the formant measurements get smeared and the nasal vowel boundaries blur together. I tested this on recordings of news anchors and street interviews, and the false positive rate jumped from around 8 percent in careful speech to over 30 percent in fast natural speech. If you need to process conversational data, you are better off switching to a manual verification step or using a different feature set based on voice quality measures like jitter and shimmer rather than pure formant tracking. Also, this method assumes you have a decent microphone. I tried it on phone-recorded audio once and the frequency response roll-off above 4 kilohertz made the nasal/oral distinction nearly impossible to detect reliably. The nasal vowels lose their spectral characteristics when you cut off the higher harmonics, and the script just starts guessing. Use a flat-response mic if you can, or at least something that captures above 8 kilohertz cleanly. For most academic and transcription purposes, the workflow I described handles the majority of cases in about 10 to 15 minutes per hour of audio once you have the scripts set up. The initial setup takes longer, probably two or three hours if you are writing the Praat scripts from scratch, but after that it runs automatically. If you need something faster and less accurate, you could skip the formant analysis and just use the aligner's stress annotations combined with a simple nasal vowel detection rule, but you will miss a significant number of borderline cases where the nasal quality is weak or the stress is on a reduced vowel.
Galeria
-

Qual é A Sílaba Tônica De Português — KERUSSO -
Classificação de Sílaba Tônica | PDF -
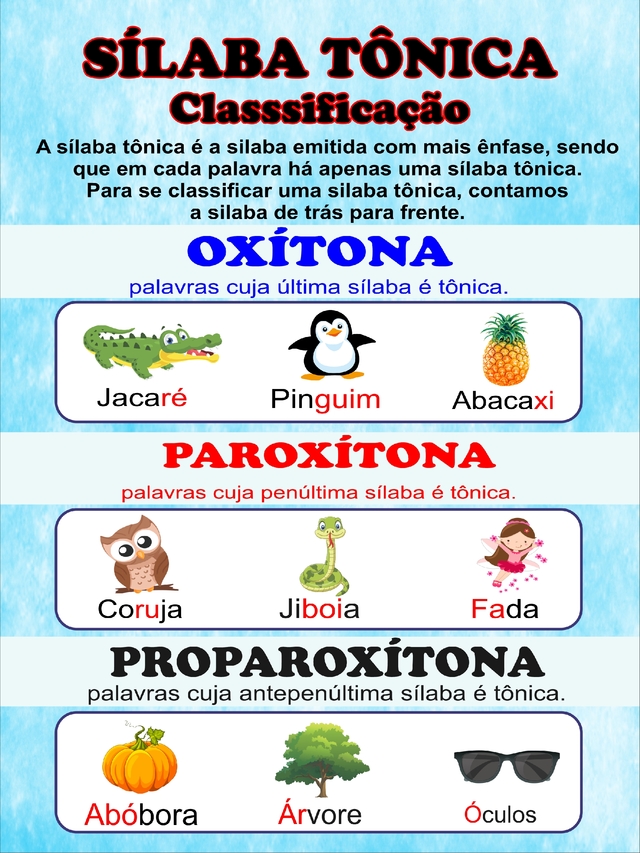
Banner de Lona Educativo Sílaba Tônica - 85x60cm -

Atividades de Sílaba Tônica para o 3º ao 5º ano

