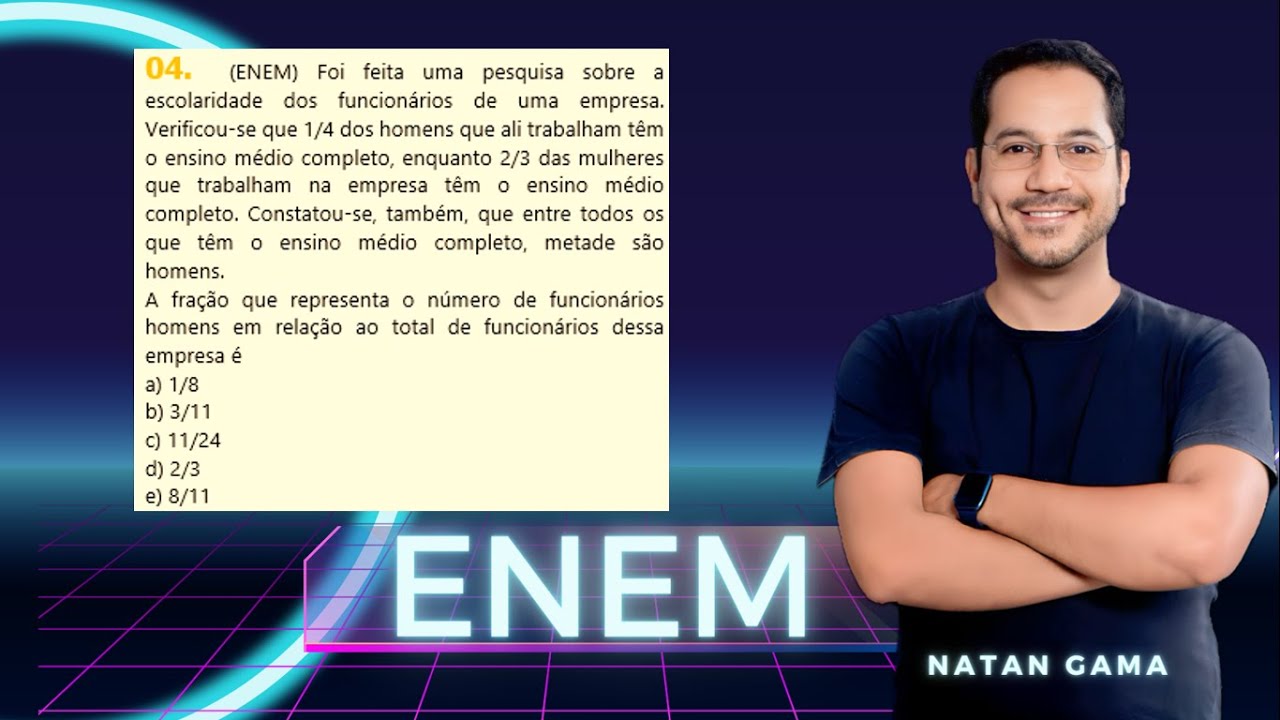
Foi Feita Uma Pesquisa Sobre A Escolaridade

Como estruturar e executar uma pesquisa sobre escolaridade de forma eficiente
Most people assume that researching education levels is straightforward. You send out a questionnaire, wait for responses, and calculate the percentages. In practice, it is much messier. I spent three years managing education surveys for regional government projects, and the biggest headaches always came from the same three sources: poor question design, missing data on edge cases, and non-response bias that quietly skews results. Here is what actually works when you need reliable data on formal schooling. The first thing most teams get wrong is treating education as a single number. Schooling is multidimensional, and flattening it into one variable destroys useful information. You need to decide early whether you are measuring years of formal education completed, highest degree obtained, literacy status, or a combination. Each choice changes the entire sampling strategy. I work with two metrics most of the time: anos de estudo concluídos and nível de instrução according to the standard IBGE classification. These align with national databases and make cross-referencing painless. If you try to build your own taxonomy, you will spend weeks reconciling formats later.
Defining the population frame is where most projects stall before they begin. You need a clear list of who counts. Is it the adult population aged 18 and over? Children aged 6 to 17 enrolled in school? Residents of a specific municipality? Once you lock the frame, you can calculate the actual sample size. For a margin of error of 3 percent at a 95 percent confidence level in a population of 100,000, you need roughly 1,800 complete responses. That number jumps to about 2,400 if you are also doing sub-analysis by region or socioeconomic stratum.
Método de coleta que evita os erros mais comuns
The most efficient approach I have used combines stratified random sampling with mixed-mode data collection. You divide the target population into strata based on geography and socioeconomic indicators, then randomly select respondents within each stratum. This prevents the data from being dominated by whichever area is easiest to access. The mixed-mode part means offering both in-person and digital survey options, because relying on just one channel systematically excludes certain groups. Question design deserves its own careful section. Here is the exact structure I use for education questions: Q1: Qual a máxima série ou grau que você completou? (Lista completa com opções de 0 a 17+ anos, incluindo analfabeto, ensino fundamental incompleto, ensino fundamental completo, ensino médio incompleto, ensino médio completo, superior incompleto, superior completo, pós-graduação) Q2: Você está atualmente matriculado em algum curso? (Sim/Não, com campo para especificar o nível) Q3: Em caso de curso superior, qual a área de formação? (Campo aberto com validação)
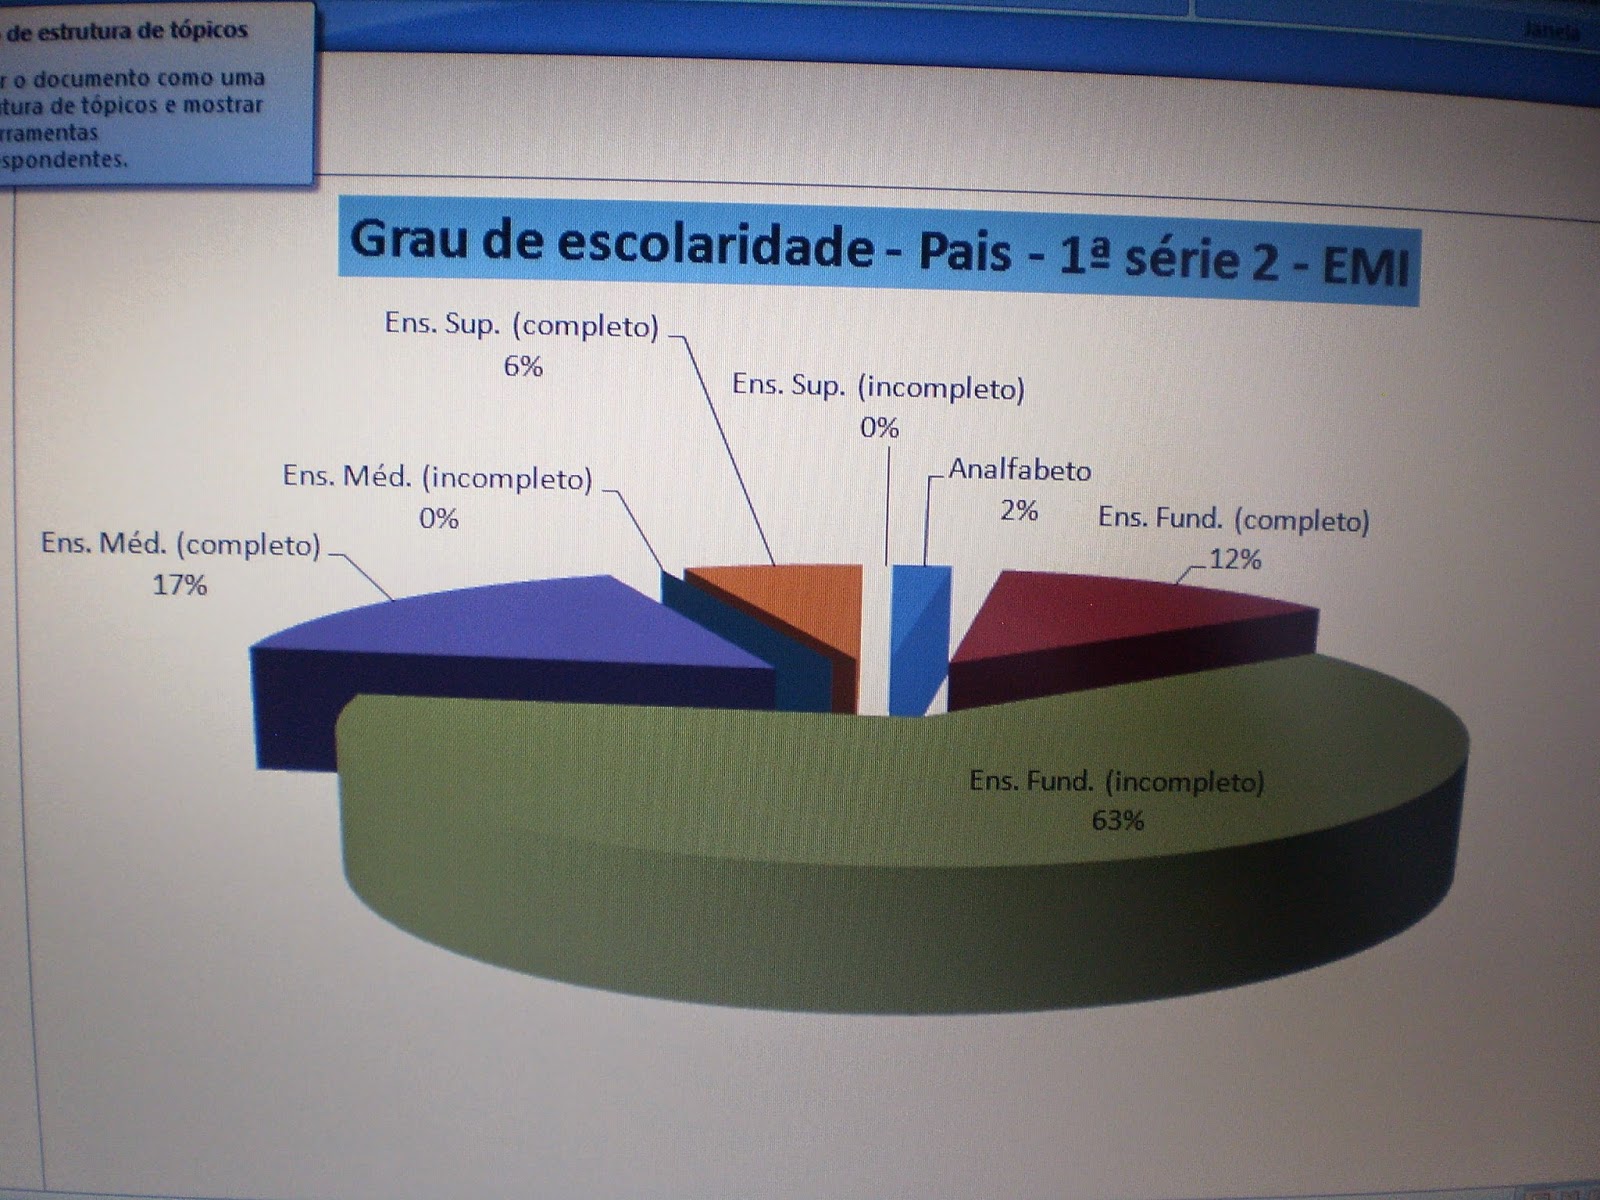
This three-question sequence catches the vast majority of cases. The key is making the options mutually exclusive and exhaustive. I once saw a survey that listed apenas diploma universitário as a single option. That lumped together someone with a two-year technologist degree and a medical doctor. The resulting data was useless for any policy analysis. Data validation happens during collection, not after. Real-time validation scripts should check for impossible responses, such as someone reporting 20 years of study but selecting high school as their highest level. The script flags these and prompts the field interviewer to confirm. This catches maybe 2 to 5 percent of responses across a typical survey, which is significant enough to matter.
O problema que ninguém te conta sobre dados educacionais
Here is a specific edge case I encountered that still comes up regularly. A region in the northeast had historically low formal education records in government databases. When we ran our survey, the reported years of schooling were consistently higher than the official municipal statistics. At first, we assumed respondents were lying or confused. After deeper analysis, the issue turned out to be the recognition of older, informal apprenticeships and community-based training programs that were counted as completed education by local residents but never entered into any official system. The workaround was simple but required a design change. I added a fourth question: Some forms of vocational training or technical courses are not always registered in official systems. Did you complete any such course? Those who answered yes were coded with a supplementary variable that adjusted the final education metric without distorting the official comparison. This kept the data usable for both internal policy work and external academic analysis.
Limitações que você precisa aceitar antes de começar
No survey on education is free from bias. Even with perfect sampling, you will have non-response rates that typically range from 30 to 45 percent in population-level studies. Those who refuse to participate tend to differ systematically from those who respond. In education research, the skew usually runs toward higher-educated individuals agreeing to surveys. The lower the response rate, the more your results will overestimate average schooling levels. The workaround for non-response bias involves post-stratification weighting. After collecting responses, you compare your sample distribution against known population benchmarks from census data. You then apply weights so that underrepresented groups exert proportionate influence in the final analysis. This does not eliminate bias but reduces it substantially. Most statistical packages handle this with a few lines of code. Another hard limit is the accuracy of self-reported education. People misremember completion dates, conflate enrollment with graduation, and sometimes inflate their highest level due to social desirability. Cross-checking with official documents when possible is ideal, but that raises privacy concerns and is rarely feasible at scale. A pragmatic compromise is to ask for the year of completion alongside the level, which gives you a consistency check. If someone claims a degree from 1995 but reports being 19 years old in 1980, the data point is flagged for review.
Ferramentas práticas para análise
For analysis, I recommend starting with R or Python using the survey package for complex sampling designs. The calculations are not difficult, but getting the sampling weights and strata right requires attention. A typical workflow takes about 4 hours for a clean dataset of 2,000 records, including cleaning, weighting, and generating cross-tabulations with confidence intervals. If you need something faster for small-scale projects, SPSS with the complex samples module handles weighted analyses well. The learning curve is steeper than Excel, but Excel is absolutely the wrong tool for anything beyond basic descriptive statistics on education data. Using unweighted averages from a stratified sample will give you biased results, and the bias grows with each additional stratum. Reporting standards matter more than most teams realize. Always include the sample size, response rate, confidence level, margin of error, and the exact wording of education-related questions. Any reader should be able to assess the reliability of the numbers without contacting you for details. This also protects you when the data gets cited by others.
Alternativas quando a pesquisa tradicional não viabiliza
Sometimes budget or timeline constraints make a full survey impossible. In those cases, you can leverage existing administrative data from the INEP or the Censo Escolar. These datasets cover virtually all enrolled students in Brazil and are updated annually. The trade-off is that they only capture enrolled populations and miss dropouts, out-of-school youth, and adult education recorded through alternative channels. A hybrid approach that I have found effective combines administrative data with a smaller targeted survey of the gaps. Use INEP data for the enrolled population and your own survey for the missing segments. Weight the combined estimates appropriately. This typically cuts costs by 40 to 60 percent while maintaining comparable accuracy for policy purposes. The bottom line is that researching education levels requires careful planning around definitions, sampling, and validation. The data is rarely clean, but it is workable if you build safeguards into the process from the beginning. Rushing the design phase saves days upfront and costs weeks of cleanup later.
Galeria
-

ENEM 2020 - 2ª APL – Foi feita uma pesquisa sobre a escolaridade dos ... -
Resolvido:(ENEM - 2020) Foi feita uma pesquisa sobre a escolaridade dos ... -

(Enem PPL 2020) Foi feita uma pesquisa sobre a escolaridade dos ...
